SIGGRAPH Asia 2026

Mise-en-Video Fine-Grained 3D Control for
Multi-Shot Video Generation

Yingshuang Zou1,*, Xiaoyu Shi2,†, Yawen Luo3, Ziang Li4, Qinghe Wang5, Mengfei Li1, Chengfeng Zhao1,
Xintao Wang2, Pengfei Wan2, Kun Gai2, Yuan Liu1,†

1The Hong Kong University of Science and Technology 2KlingAI Research 3The Chinese University of Hong Kong 4Northwestern Polytechnical University 5Dalian University of Technology

Stage every shot in 3D, then generate a coherent story with precise control over subject placement, motion, and orientation.

DOI

*This work was conducted during the author's internship at KlingAI. †Corresponding authors.

Explore
Overview

Direct Every Shot

Abstract

Recent advances in text-to-video generation have enabled high-fidelity single-shot synthesis, yet practical storytelling creation requires multi-shot videos with both strong inter-shot consistency and fine-grained controllability. We propose Mise-en-Video (MeV), a highly controllable multi-shot video generation framework that lets creators stage shots in 3D and generate the corresponding video. To achieve this, our framework combines a hierarchical attention mechanism for multi-level narrative consistency with 3D-aware layout guidance for precise, per-shot spatial control. To support training and evaluation, we develop standardized annotation pipelines and construct a 160K-video dataset with hierarchical multi-shot texts and oriented 3D bounding boxes. Extensive experiments demonstrate that MeV consistently outperforms strong baselines in video quality, inter-shot consistency, and subject-level controllability.

01 — Text control

Shape the Story
Across Shots

Hierarchical captions separate the global story from shot-level action and subject-level appearance, preserving intent across cuts.

Global caption

Whole sequence

In a dimly lit indoor setting, three professionals—a man with glasses, a woman, and another man—engage in a serious conversation, captured through close-up shots that emphasize their expressions and interactions.

Read full global caption

There are three main subjects in the video. The first is a Caucasian man in his early 30s with short, dark brown hair, wearing black-rimmed glasses, a light blue collared shirt, and a black tie. The second subject is a Caucasian woman in her 30s with her light brown hair pulled back. She is wearing a dark blazer over a dark collared shirt. The third subject is a Caucasian man in his 30s with short, dark brown hair, wearing a dark jacket over a light blue collared shirt. The scene is set in a dimly lit indoor environment, a laboratory. The background is dark and out of focus, creating a shallow depth of field. In the background behind the first man, there is a bright, rectangular light source with a blueish-white glow, and some indistinct shapes. Behind the woman, there are vertical, metallic-looking structures with a cool, bluish light reflecting off them. The overall lighting is low-key and dramatic, with key lights illuminating the characters' faces while the rest of the scene remains in shadow. Realistic. It appears to be a TV series or movie scene with artificial lighting, creating a focused and somewhat dramatic effect on the subjects. The color tone is muted, with a cool palette dominating the visuals, contributing to a serious and professional atmosphere. The scene has high saturation, moderate contrast, moderate brightness and normal color temperature.

01

Shot caption

Shot 01 / 04
  1. [Shot 1] The video starts with a close-up shot of a man with short brown hair and glasses, wearing a light blue shirt and a dark tie. He has a serious and attentive expression as he looks slightly to his right, listening to someone off-screen. The camera slightly shakes, with a shallow depth of field. The lens is roughly at the same height as the man, capturing a close-up of his front and side profile. The man is positioned on the left side of the frame.
Global caption

Whole sequence

In a dimly lit, wood-paneled room, a young woman, a man in a tan suit, and another man in a dark suit engage in a serious conversation, captured through close-ups and medium shots.

Read full global caption

There are three main subjects in the video. The first is a young adult Caucasian woman with dark, curly, shoulder-length hair styled in a vintage fashion. She is wearing a light-colored, beige, collared jacket. The second subject is a young adult Caucasian man with short, dark, wavy hair. He is wearing a tan suit jacket, a white collared shirt, and a patterned tie with brown, white, and dark colors. He is seated at a desk. The third subject is a middle-aged Caucasian man with short, slicked-back, graying hair. He is wearing a dark suit jacket, a white collared shirt, and a red and gold patterned tie. The scene is set in a dimly lit room with a serious and somber atmosphere. The walls are a dark, muted green color. In the background, there is a window with a dark wooden frame and a textured, frosted glass pane. The room is illuminated by warm, soft light from two wall-mounted sconces with exposed, round light bulbs, one on each side of the frame. A dark wooden desk is visible, upon which the man in the suit is sitting. The overall lighting is low-key, creating strong shadows and highlighting the characters' faces. Realistic. It appears to be a scene from a TV series or movie, exhibiting a realistic style with a nostalgic filter. The lighting is primarily artificial, creating a dimly lit and somewhat somber atmosphere. The color tone is muted, with a focus on earth tones and desaturated colors, contributing to the vintage aesthetic. The scene has medium saturation, moderate contrast, moderate brightness and neutral-toned colors.

02

Shot caption

Shot 01 / 04
  1. [Shot 1] The video opens on a medium close-up of a woman with dark, curly hair, wearing a light-colored coat. She is in a dimly lit room with a textured glass window behind her. She has a somber and concerned expression as she looks slightly down and to her right. She then slowly turns her head to her left, her expression remaining serious and watchful. The camera slightly shakes, with a shallow depth of field. The lens is roughly at the same height as the woman, capturing her profile in close-up. The woman is positioned on the left side of the frame.
02 — Spatial control

Stage Subjects in 3D

NOCS-encoded oriented 3D boxes guide where a subject appears and which way they face. The inset in each result shows the layout signal used for generation.

03 — More results

Generated Multi-Shot
Sequences

Diverse subjects, settings, shot lengths, and camera perspectives—generated as coherent multi-shot sequences with explicit spatial guidance.

04 — Method

How Mise-en-Video
Works

MeV couples a lightweight 3D staging interface with text that understands the whole story, each shot, and every subject.

01

Stage, describe, generate

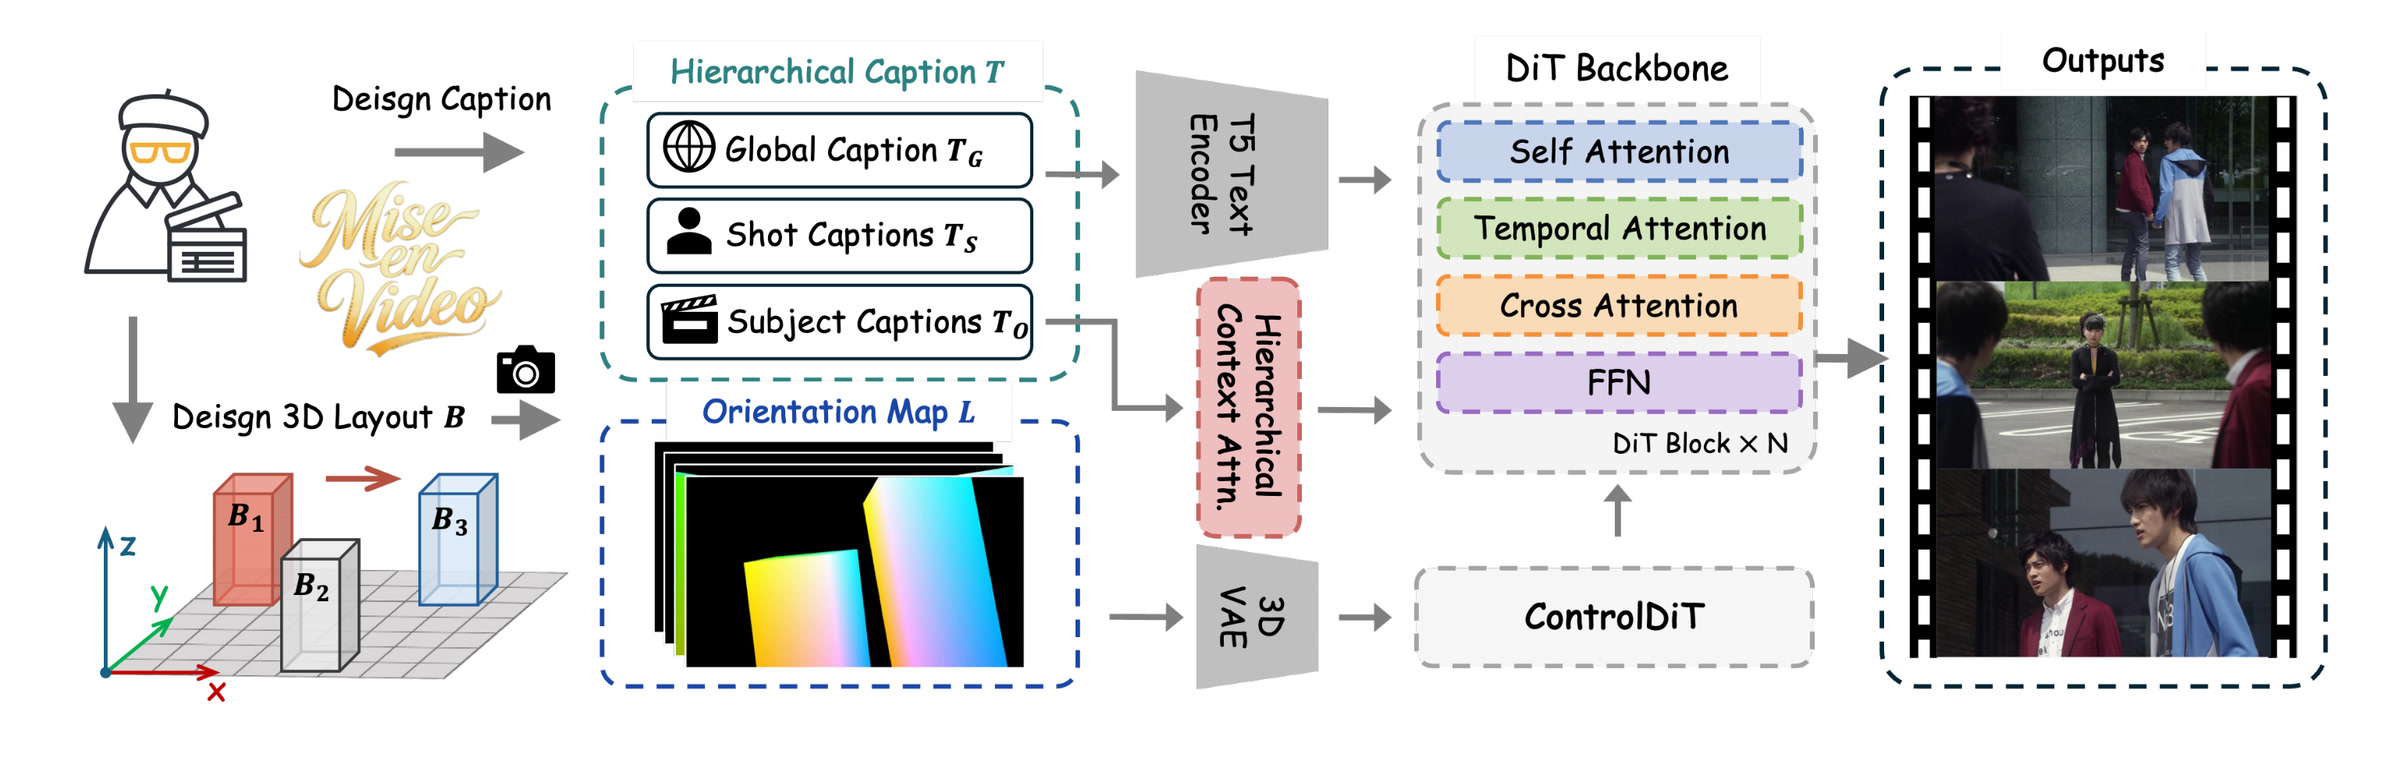
Creators provide a hierarchical caption and an oriented 3D layout. The layout is projected into NOCS orientation maps and encoded as a video condition. A ControlDiT branch injects that condition into the pretrained DiT while the caption guides appearance, action, and narrative continuity.

Overview of the Mise-en-Video generation pipeline
Figure 2 · System overview
02

Attention with boundaries

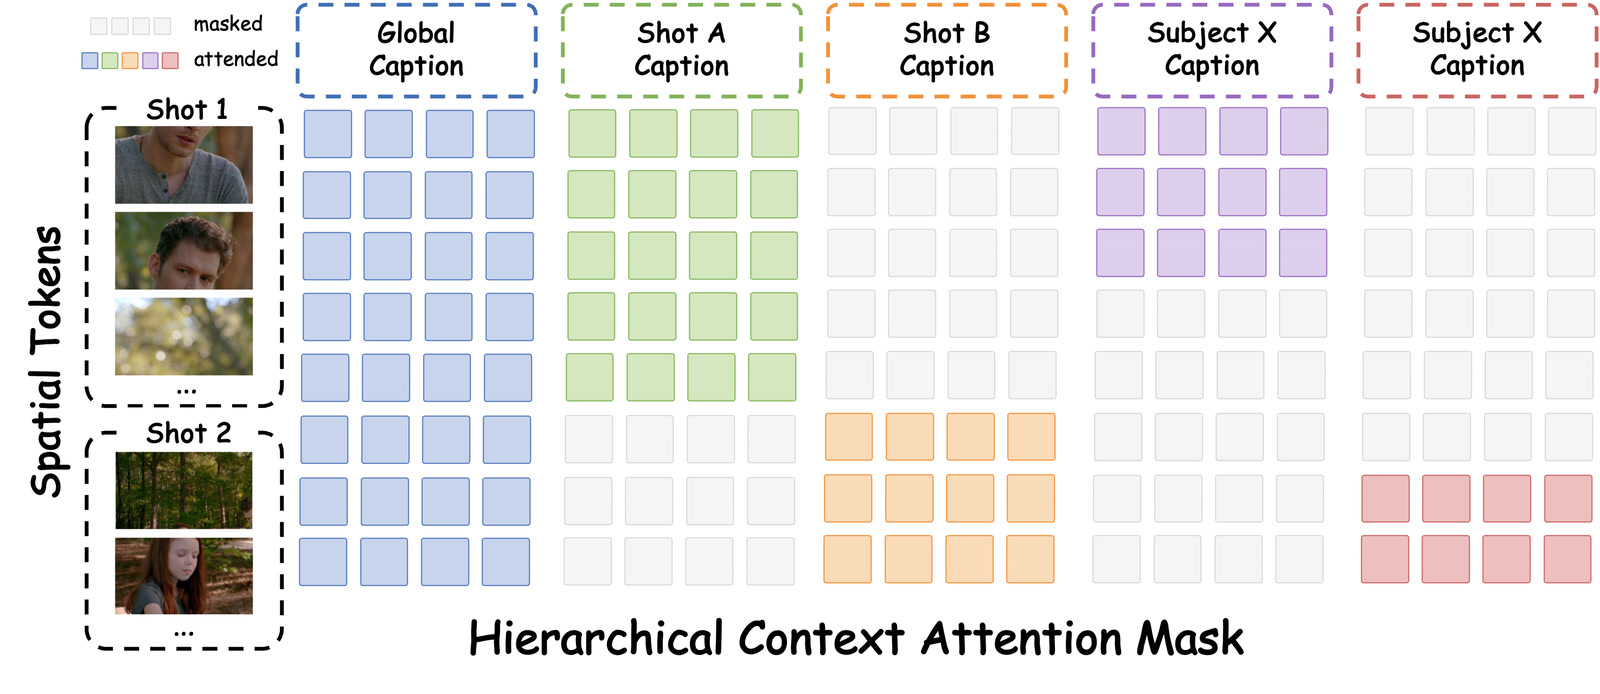
Hierarchical Context Attention prevents semantic leakage. Global text is visible to every visual token; shot text only reaches its matching shot; subject text is restricted to tokens inside that subject’s projected space-time region.

Hierarchical context attention mask
Figure 3 · Hierarchical Context Attention
03

Scalable Training Data Generation

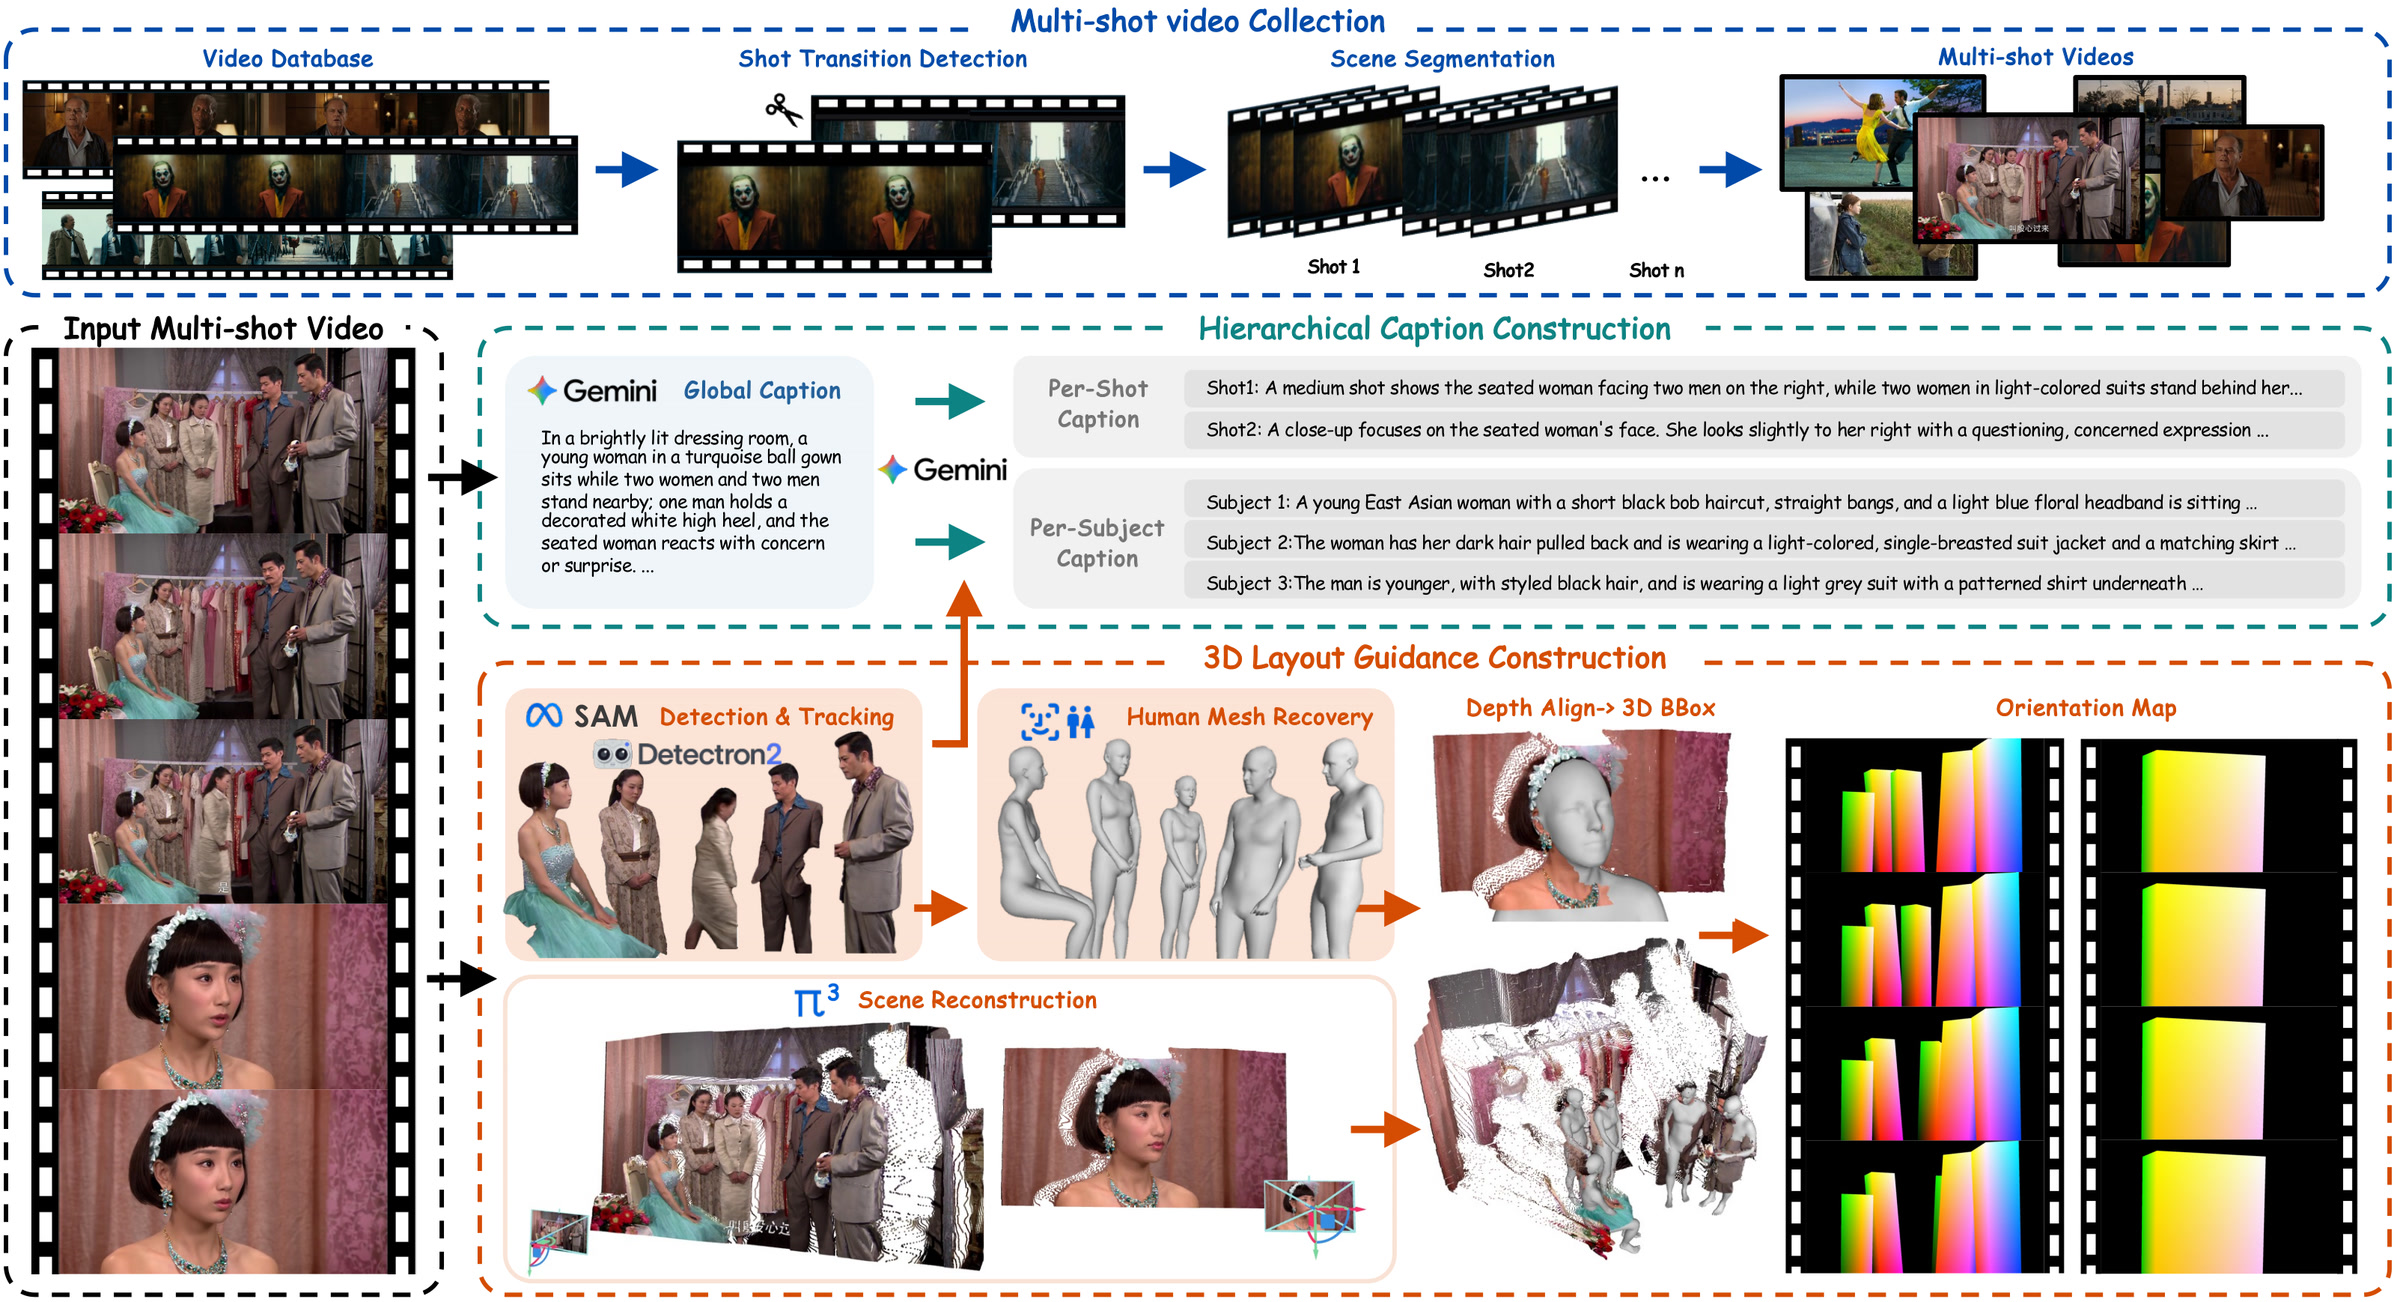
Raw videos are split into multi-shot samples. Subjects are detected, tracked, and reconstructed as 3D meshes; scene depth aligns them in one coordinate system, then oriented boxes become NOCS maps. In parallel, global, shot, and subject captions are generated with consistent subject identities across cuts.

Multi-shot video data annotation pipeline
Figure 4 · Data creation pipeline

05 — Citation

BibTeX
@inproceedings{zou2026mise,
  title     = {Mise-en-Video: Fine-Grained 3D Control for Multi-Shot Video Generation},
  author    = {Zou, Yingshuang and Shi, Xiaoyu and Luo, Yawen and Li, Ziang and
               Wang, Qinghe and Li, Mengfei and Zhao, Chengfeng and Wang, Xintao and
               Wan, Pengfei and Gai, Kun and Liu, Yuan},
  booktitle = {SIGGRAPH Asia 2026 Conference Papers},
  year      = {2026},
  publisher = {Association for Computing Machinery},
  doi       = {10.1145/3829340.3842208}
}